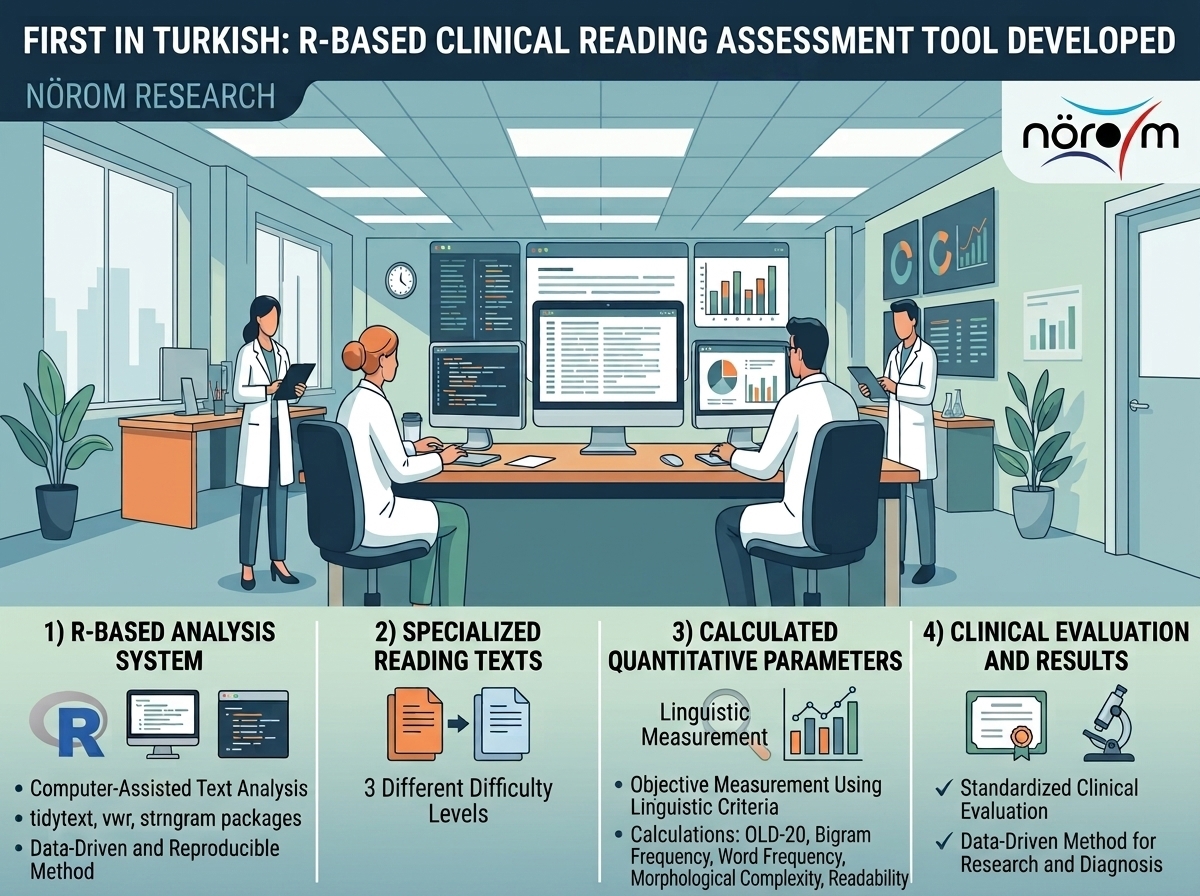
The clinical, scientific, and accurate assessment of reading skills relies on evaluating the texts used during the testing phase according to objective linguistic criteria. In a new and pioneering study conducted within NÖROM, an R-programming language-based, computer-assisted text analysis tool was developed to quantify the properties of the texts used in these assessments. The study successfully proved the efficacy of this newly developed system by testing it on specially generated texts.
Special Reading Texts at Three Different Difficulty Levels
Within the scope of the study, NÖROM researchers not only developed an analysis tool but also produced standardized texts that could be tested on this tool. Two main texts were authored and prepared at three levels of linguistic and structural complexity. These were designated as the narrative text titled "Çifte Sürpriz" (Double Surprise) and the informational text titled "Deniz Yıldızları" (Starfish). These original contents aim to establish a scientifically grounded foundation for clinical evaluation and diagnostic processes.
Comprehensive Tests and Calculation of Quantitative Parameters
Aiming to reveal the structural characteristics of the texts with mathematical precision, NÖROM researchers used the "tidytext", "vwr", and "strngram" packages in R to analyze the generated texts. As a result of six separate tests performed using the developed tool, critical quantitative parameters—such as the orthographic similarity (OLD-20) of the texts, bigram frequency, word frequency, morphological complexity, and readability levels—were calculated from numerical data.
Standards Established for Clinical Evaluations
As a result of these intensive computer-assisted analyses, it was determined that the texts coded as M2a and M2b shared the closest characteristics in terms of the calculated linguistic parameters. Thanks to this new analysis tool developed by NÖROM, concrete, unbiased, and quantitative criteria have been established for Turkish texts to be used in measuring reading skills and in clinical diagnostic processes.
The results demonstrate that a text analysis tool developed in R has been successfully developed and tested for the first time in Turkish. This study, conducted at NÖROM, advances the scientific standards of Turkish reading materials for both academic research and clinical diagnostic applications by offering a fully data-driven and reproducible method for quantitative text evaluation.
First in Turkish: R-Based Clinical Reading Assessment Tool Developed
Researchers at NÖROM Discover Protein Connection Between Chronic Migraine and Cognitive Complaints
First, They Spiked in Their minds, Then They Became World Champions!
Prof. Hayrunnisa Bolay Belen Elected to the YÖK Executive Board